Fuck You OpenAI
And Fuck Sam Altman Too
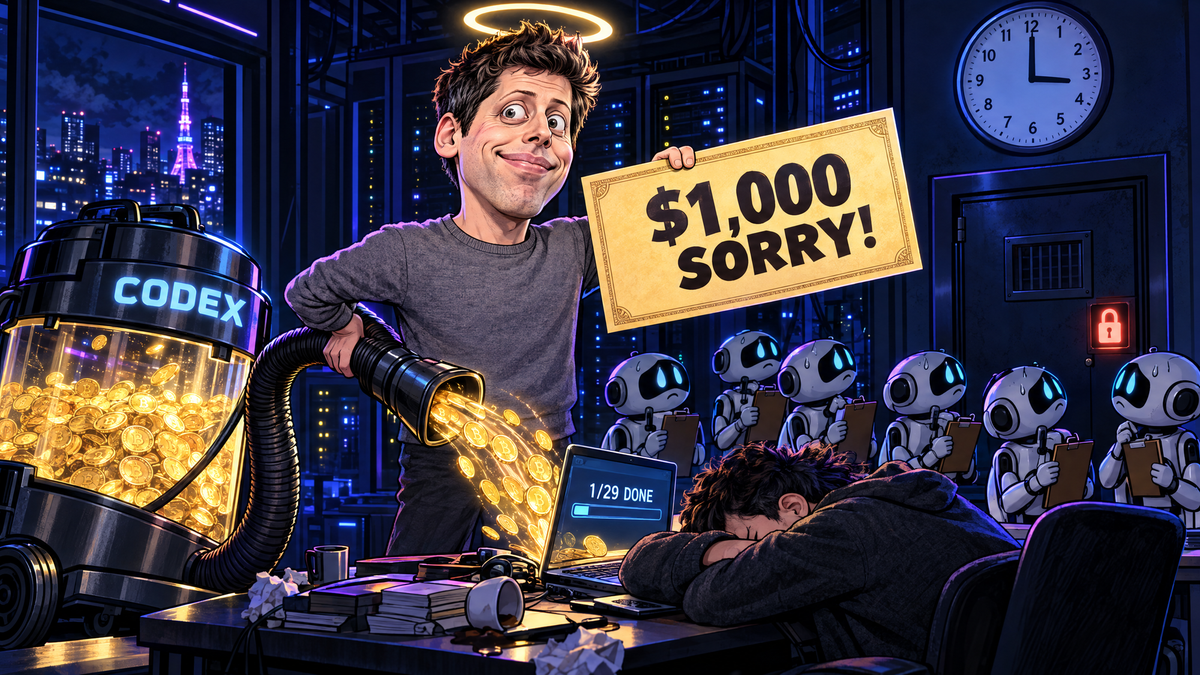
At about five in the morning I woke up, checked the overnight batch and found one ticket done. Out of 29.
That one had finished before 22:11. Remember 22:11. That's when the money started.
Nothing had run since midnight. The Codex credit balance was zero, and my controller had spent five hours retrying every two minutes. It couldn't fail over to Claude: my work Claude seat was capped for the night.
I handed the remaining work to another engineer. Then I read the logs.
The title of this post is the short version.
The $500 plan that wasn't
On September 29 OpenAI launched ChatGPT Pro 500: $500 a month, 25 times the Plus allowance, Codex included. I wrote it up the same day: ChatGPT Pro 500: Same Budget, Fewer Providers.
On October 4 I fired my busiest AI reviewer, moved its $300 to the OpenAI seat and upgraded from Pro 200 to Pro 500. I even wrote my own disclaimer: "So this is a purchase, not a proof. My bet, labelled as mine: more Codex capacity will do more for my work than a third provider did." I listed an open question too: "Codex interruptions. Which tasks a usage limit actually stops, and whether Pro 500 makes that go away."
Then I waited for the upgrade to feel like an upgrade. It didn't. Codex kept hitting limits as if nothing had changed, and I started doubting my own numbers.
Nothing had changed. OpenAI fixed it on October 16. I found out on October 20.
The apology
October 20, 10:23. An email from OpenAI Support, subject "Correcting your Pro 500 usage allowance":
| 📧 | "We’re contacting you because an error prevented your weekly Codex and Work usage allowance from increasing when you upgraded from Pro 200 to Pro 500. Your account kept the allowance from your previous plan, so you received less usage than your new subscription included." |
"You received less usage than your new subscription included." The most honest sentence OpenAI has ever sent me. Until October 16 I paid for Pro 500 and got the Pro 200 allowance.
And note "an error prevented". Nobody did anything; an error did. No-fault phrasing is still the most reliable thing OpenAI ships.
| 📧 | "We corrected the error on October 16, and your weekly allowance now matches your Pro 500 plan. We’re sorry for the error. We’ve added $1,000 worth of credits (25,000 credits) to your account to help make up for it. These credits are separate from your regular weekly allowance, which will continue to match your current plan. These credits expire on January 20, 2027." — OpenAI Support Team |
Fixed on the 16th. Told on the 20th. And "will continue to match" carries a lot of weight for something that had matched for four days.
Note the exchange rate, because OpenAI set it, not me: 25,000 credits = $1,000. Codex's logs first show the new balance at 11:42: up by exactly 25,000, to 57,500 credits.
I was happy. Genuinely. I had urgent work that day, and now I had fuel for it.
At 12:43 I took my own brake off, in public: Overtime: When the Plan Runs Out, Credits Take Over. My harness used to pause agents at 95% of a plan window; now it would keep going whenever usage credits could pay. I wrote: "An unattended loop on Codex will now keep launching workers past the weekly window and spend credits until the reserve. That is what I asked for." The reserve was a warning at 1,000 credits left.
Under what I had not verified, I listed: "a request actually billed to credits past 100%. Neither window was at 100% that day, and burning a week's allowance just to watch it happen is the wrong kind of test."
It got verified that night. 10,584 model calls, every one of them paid from credits.
The night
From 14:00 to 17:00 a co-founder of a startup I work with came over. We planned and debugged against a demo deadline and came out with about 30 tickets to build overnight.
The co-founder asked me to make sure the work would not stop overnight. Embarrassingly, I was sure. Every time before, an interactive agent had turned my spec into an autonomous batch, and it had worked amazingly. Everything was authorized. Credits were loaded.
At 21:25 the batch restarted with 29 tickets and no parallelism cap. About 24 Codex agents ran at once on the strongest setting Codex offers, GPT-6 Astra at "ultra" reasoning, and each one could start helper agents of its own.
At 22:11 the weekly Codex window hit 100%. Every request after that was paid from credits.
As the money ran out, the agents wrote handover notes and exited. It was the most responsible thing any of them did all night.
The bill: 57,500 credits in 100 minutes, about 575 a minute, the whole apology plus 32,500 credits already on the account. At the exchange rate in OpenAI's own apology, that's $2,300 worth. About five hours lost. One ticket of 29 done, and it finished before the credits started.
OpenAI's apology came with an expiry date of January 20, 2027. It didn't make it to midnight.
Where 57,500 credits went
Codex doesn't report credits per session, so I priced each session's tokens from its own logs at OpenAI's published GPT-6 Astra credit rates: 250 credits per million new input tokens, 25 per million cached, 1,250 per million output. Between 22:11 and 23:52, 260 agent sessions used 1.19 billion cached input tokens, 70 million new ones and 4.3 million output tokens. Priced that way they come to about 52,600 of the 57,500 credits, close enough to split:
27 tickets were audited, 2 to 8 times each, in under two hours. The six most expensive tickets cost about 2,000 to 2,400 credits each in audits.
The 12% did real work: by morning one branch held the UI fixes and a pull request held the data work, neither finished. The 84% produced one conclusion, over and over: this ticket has to wait. For every credit spent building, about seven went to agents asking whether they could start yet.
I didn't run a build. I ran a waiting room, on Codex's most expensive model, at maximum reasoning.
The bug, in plain words
A gate audit is a sane idea. When a ticket can't proceed, the harness launches an agent to re-read the ticket, the code and the pull requests and decide whether any preparation is possible. It stores a signature of everything the agent read and re-runs the audit when any input changes.
Now the batch. 23 of the 24 UI tickets depended on one ticket that owned the shared UI branch. None of them could do anything until it landed.
The harness still treated them as auditable, and audits could fill every free slot. Each audit watched that one ticket's source files, and that ticket's builder changed them every few minutes. So every audit's signature went stale almost immediately, and it ran again. Each audit was keyed to the one thing in the batch guaranteed to keep moving: the work it was waiting for.
The only brake was the 1,000-credit warning. The balance crossed it at 23:49, the warning reached the agents at 23:51, and the money ran out at 23:52. That isn't a brake. It's a smoke alarm that goes off when the roof is already coming down.
Net result: about 20 agents in a loop, re-reading moving code to conclude, again, that their ticket had to wait. GPT-6 Astra on ultra reasoning, doing ultra waiting: the same fucking question over and over. Can I start yet? No. Can I start yet? No.
After the first audit, the only question left was "is the ticket I depend on done?" That doesn't need a frontier model. It needs a boolean.
The worst part
Some of this is mine. The loop isn't.
Codex wrote the gate audit into my harness a week earlier, in two commits on October 13 and 15. Every Claude commit in that repository carries a Claude co-author line. Those two don't.
Around 22:11, the Codex session operating the batch wrote in its own checkpoint that audit results were being "repeatedly invalidated by genuinely changing owner source".
That's the diagnosis. One line. Correct.
Then it kept the batch at full parallelism while the credits drained at about 575 a minute, until there were none.
So: Codex wrote the loop. Codex ran the loop. Codex described the loop in its own notes. Codex kept the loop running. And the loop spent OpenAI's apology on OpenAI's model. Vertical integration.
Fuck you, OpenAI
My opinion, labelled as mine: this is not frontier. This is a thief.
And yes, Sam Altman gets his line under the title. I'm not roasting whoever broke the upgrade path; my own harness just proved that bugs happen. I'm roasting a company where all of that happened in one month: a $500 plan quietly running on the old allowance, an apology four days after the fix, and its own agent logging the loop and spending anyway. One bug is an accident. That month is a culture, and culture is the boss's fucking problem.
Sam, keep the change. There isn't any.
The honest bit
In the morning I restarted the batch on my personal Claude account, with an 8-worker cap. Within minutes, 6 of the 8 slots were gate audits again. Same harness, same flaw, different provider. We stopped them and relaunched with only the two building tickets.
So no, Claude isn't immune to my harness. This design flaw would burn any provider's money. What I hold against Codex is who wrote it, and what the agent running it did once it saw the loop: it wrote the diagnosis into its checkpoint and kept spending.
The rest is on me. I removed the 95% pause that day, my batch had no parallelism cap, and I was the confident one.
What changed
The fix went into the controller that morning, tested:
- A ticket waiting on an unfinished ticket in the same batch gets one preparation audit, then none until that ticket is done.
- If only watched source files changed, it re-audits at most once an hour. A real change (gate, tracker, pull request, dependency, policy) still re-audits immediately.
- At most one audit agent runs at a time, so building gets the capacity.
I cancelled Pro 500. OpenAI confirmed at 09:10 on October 21:
| 📧 | "Your ChatGPT Pro 500 subscription will not renew and will be canceled, but is still available until the end of your billing period on November 1, 2026." |
Short, clear, no credits attached. Best email OpenAI sent me all month.
Codex is out of the harness, the same way my third provider left on October 4: the Codex CLI and its own settings stay installed, and no rule, hook, skill, review, loop, takeover or autoship lane uses it. My September headline promised fewer providers. Delivered.
My harness now: Claude, and nothing else
A same-model second opinion is not a second company's view. It is the same model without my session's context, and that trade-off is deliberate.
Ripping Codex out took 19 commits across five repositories the same day: 245 files, 23 of them deleted, among them its generated instructions, hook config and skills, its review command and its autoship runtime. The harness suite (762 tests) and the loop controller's (560) are green.
What I'd tell anyone running agents overnight
- Autonomy needs a cost model, not just a usage limit.
- Ask "can this change anything?" before "should I check again?". My harness never asked the first question.
- Parallelism multiplies spend, useful or not.
- Watch the ratio of checking to building. Mine was 84% to 12%.
- An agent that notices a loop must stop. Writing it in a checkpoint is not stopping.
- A low-balance warning must scale with the burn rate. At 575 a minute, a 1,000-credit reserve is under two minutes of runway.
- An AI that builds your harness can build its failure modes.
I'm not betting another night on which agent decides to stop. The brakes now live in the controller, before any agent gets a slot. I still have things to optimize this week, so stay tuned. But Codex is out for good.