Don't Let the Safecracker Grade the Job
A crew of AI agents beats one strong agent when the work splits cleanly and someone other than the worker checks it. Otherwise it costs more and fails in more places.
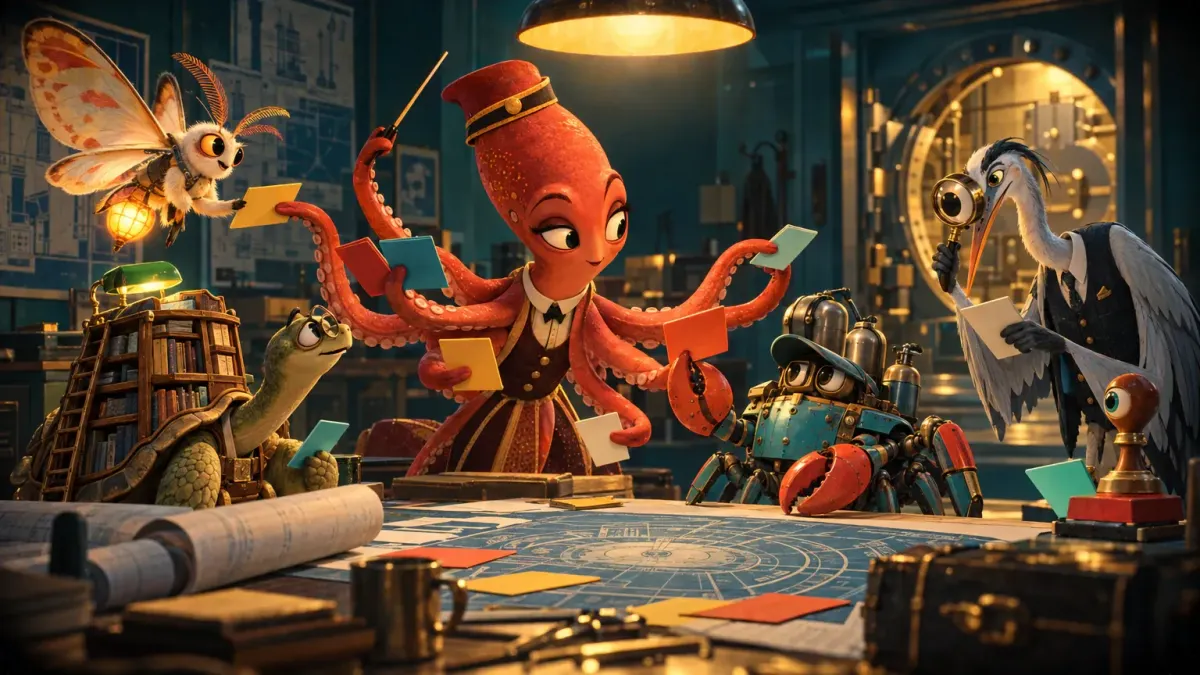
Heist films run on a familiar structure. One person can't crack the vault alone, so the crew comes together, the plan gets laid out on a table, everyone runs their part at once, something goes wrong, and someone has to catch it.
Coding agents can work the same way. You can hand a task to one strong agent, or to a crew: a lead that briefs specialists, each with its own context, its own tools and sometimes its own model. The film above casts that crew as a lead who briefs everyone at once, a scout, a researcher, an implementer, a reviewer and a verifier. This article is the version without the lasers: when a crew beats one strong agent, when it quietly burns money, and how to set up your first one tomorrow.
Every number below comes from a primary source read on 20 November 2026, except my own small bench, which is labeled as such. Vendor numbers are labeled as vendor numbers.
Start here
| 🧭 | Your first crew, tomorrow morning. You need three subagents in Claude Code: a read-only explorer, an implementer and a skeptical, read-only reviewer. Your main session is the lead. Per the subagents docs, each subagent "runs in its own context window with a custom system prompt, specific tool access, and independent permissions." Each one is a short Markdown file: the frontmatter holds 1. Explorer. 2. Implementer. 3. Reviewer. The first session. Pick a real, small task, say per-IP rate limiting on a login endpoint. Type, one at a time: "Use the explorer subagent to map how requests reach the login handler and where middleware is registered; return paths and a ten-line flow." Agree a plan with the lead. Then: "Use the implementer subagent. Objective: the sixth login attempt per minute per IP is rejected. Output: diff summary and test results. Boundaries: the middleware file and its tests only." Then: "Use the reviewer subagent on the changes to the middleware file and its tests: correctness, how the limiter key can be spoofed, test coverage." How it ends. The reviewer returns findings, you decide which are real, the implementer fixes those, and you merge. Your main context never filled up with grep output or test logs, and nobody on the crew said "ship it". That stays with you. |
Why crews work: tokens and clean rooms
Anthropic's multi-agent research post (June 2025) says it plainly: "Multi-agent systems work mainly because they help spend enough tokens to solve the problem." In its BrowseComp analysis, "token usage by itself explains 80% of the variance," and with tool calls and model choice, three factors explain 95% (Anthropic's own analysis).
That system ran an Opus 4 lead with Sonnet 4 subagents, and on Anthropic's internal research eval it "outperformed single-agent Claude Opus 4 by 90.2%." That is the vendor's number on the vendor's eval: a direction, not a guarantee. The same post adds a check on the token story: "upgrading to Claude Sonnet 4 is a larger performance gain than doubling the token budget on Claude Sonnet 3.7." Here, more of a weaker model lost to a better one.
The second mechanism is separate context. Subagents work "in parallel with their own context windows" and condense "the most important tokens for the lead," and each brings "distinct tools, prompts, and exploration trajectories—which reduces path dependency." For coding, that last phrase is the important one. An agent forty turns into one theory of a bug is anchored to it. Claude Code's agent teams docs name the problem: "Sequential investigation suffers from anchoring: once one theory is explored, subsequent investigation is biased toward it." Independent investigators who try to disprove each other correct for it. One agent rereading its own work does not.
When the work truly fans out, parallelism also buys time: a lead starting 3–5 subagents at once, each using tools in parallel, "cut research time by up to 90% for complex queries" (again Anthropic's measurement).
The briefing is the heist
In the film, the briefing gets its own scene. Real systems need that part most, because the briefing is where crews often fail.
A subagent knows nothing you didn't tell it. It "doesn't see your conversation history, the skills you've already invoked, or the files Claude has already read." Anthropic lists what each one needs: "an objective, an output format, guidance on the tools and sources to use, and clear task boundaries." And what happens without them: "agents duplicate work, leave gaps, or fail to find necessary information."
In coding terms:
- Objective: the outcome, not the activity. "Login rejects the sixth attempt per minute per IP," not "look at rate limiting."
- Output format: what comes back and how long. Unconstrained, you get an essay, and the lead's context fills with exactly what the subagent was meant to keep out.
- Tools and sources: which directories, which test command, which docs. The tool rules enforce the hard limits; the brief covers the rest.
- Boundaries: which files it may touch, which it must not, and when to stop and ask.
If you can't write those four lines, the task isn't ready to delegate. It is still a thinking task, and thinking belongs in the main session.
Don't let the safecracker grade the job
Anthropic's harness design post (March 2026) found that "when asked to evaluate work they've produced, agents tend to respond by confidently praising the work—even when, to a human observer, the quality is obviously mediocre." The fix was structural: "Separating the agent doing the work from the agent judging it proves to be a strong lever," and "tuning a standalone evaluator to be skeptical turns out to be far more tractable than making a generator critical of its own work."
That is why the reviewer above has no Write, Edit or Bash tools and starts from the assumption that a bug exists: its only job is to find problems.
The pattern scales. The subagents docs allow nesting "up to three layers below the main conversation," and their example is "a reviewer subagent that dispatches a verifier per finding." Anthropic's Code Review works the same way: its agents "look for bugs in parallel, verify bugs to filter out false positives, and rank bugs by severity." By Anthropic's internal figures, PRs with substantive review comments went from 16% to 54%, and "less than 1% of findings are marked incorrect." Vendor numbers, but the design point stands on its own: one agent finds, a different one checks.
Split the review by concern, too. The agent teams docs note that "a single reviewer tends to gravitate toward one type of issue at a time," and suggest separate reviewers for security, performance and test coverage.
There is a catch: the judge has to be right. Nicholas Carlini's C compiler post puts it bluntly: "it's important that the task verifier is nearly perfect, otherwise Claude will solve the wrong problem." A skeptic with vague criteria produces confident noise. Give it the same four-part brief you give the implementer.
When the heist goes wrong
Everyone on the same lock
Carlini set 16 agents to build a Rust-based C compiler. Over nearly 2,000 sessions and about $20,000 in API costs, they produced a 100,000-line compiler that builds Linux 6.9 on x86, ARM and RISC-V (it still calls out to GCC for 16-bit boot code and "does not have its own assembler and linker").
The instructive part is where it stalled: "compiling the Linux kernel is one giant task. Every agent would hit the same bug, fix that bug, and then overwrite each other's changes. Having 16 agents running didn't help because each was stuck solving the same task." The fix was not more agents. It was a way to split the work: GCC "as an online known-good compiler oracle to compare against," which turned one giant failure into many small independent ones. If your task has one critical path, a crew means several agents colliding on it, each burning tokens.
Sequential work and shared context
Anthropic's 2025 post warned that "most coding tasks involve fewer truly parallelizable tasks than research." The subagents docs say to stay in the main conversation when "multiple phases share significant context, such as planning, implementation, and testing," or when "latency matters." The agent teams docs agree: "For sequential tasks, same-file edits, or work with many dependencies, a single session or subagents are more effective." OpenAI's Codex subagents docs warn about "write-heavy workflows, because agents editing code at once can create conflicts and increase coordination overhead."
So the later successes don't overturn the 2025 caveat; they route around it. Code Review parallelizes reading. The compiler parallelized independent test failures.
Errors that multiply
Google Research and DeepMind's scaling paper (v3, April 2026) tested 260 configurations across six benchmarks, five architectures and three model families. Against a single agent, multi-agent results ranged "from +80.8% on decomposable financial reasoning to -70.0% on sequential planning." The same idea helps a lot or hurts a lot depending on the shape of the task.
On errors, independent agents "amplify trace-level errors 17.2×," while centralized coordination "contains this to 4.4× by enforcing validation bottlenecks." Note that 4.4× is still amplification: a lead and a verifier contain compounding errors, they don't remove them. As Anthropic's post says, "Agents are stateful and errors compound."
The cut: what a crew costs
Every figure here comes from the company selling the tokens:
Subagents are the cheap option: results come back summarized, and the docs list routing work to Haiku as a cost lever. Agent teams are the expensive one, because each teammate is a separate Claude instance. The research post states the rule: multi-agent systems "require tasks where the value of the task is high enough to pay for the increased performance." The harness post sharpens it: the evaluator "is worth the cost when the task sits beyond what the current model does reliably solo."
One lever the sources hint at and I use: give each role the model and effort it needs, not the lead's. My own harness runs a crew like the one in the film, each role on its own row of a routing table. On a small bench of my own tasks (two or three runs each, tasks shorter than real work), the reviewer at high effort found every seeded bug that max effort found, at about a fifth of the cost, and the implementer at high did no worse than at xhigh, one level up, at 39% of the cost. A small sample, not a law. But it's a cheap experiment to run on your own crew: measure each role, then pay for the effort only where it changes the result.
Growing the crew
More subagents, same lead. Add specialists: a test-gap reviewer, a security reviewer, a verifier the reviewer dispatches per finding. Every result still comes back through the lead, which keeps the validation bottleneck the scaling paper credits with containing errors.
Agent teams. Experimental and off by default: set CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1 in settings or the environment. Teammates "share a task list, claim work, and communicate directly with each other," and Anthropic's Opus 4.6 announcement (5 February 2026) calls them "best for tasks that split into independent, read-heavy work like codebase reviews." Start "with 3-5 teammates"; "three focused teammates often outperform five scattered ones." There are no nested teams, and the lead is fixed for the session's lifetime.
Either way, the 2024 advice from Anthropic's Building effective agents still holds: "find the simplest solution possible, and only increase complexity when needed. This might mean not building agentic systems at all."
Crew or solo?
TL;DR
- Crews work mostly because they spend more tokens in separate, uncluttered contexts, and results scale with how well the task splits.
- Start with three subagents: a read-only explorer, an implementer and a read-only skeptical reviewer. Your main session is the lead.
- Brief every subagent with an objective, an output format, its tools and sources, and its boundaries. Can't write the brief? Don't delegate.
- Never let the worker grade its own work. A separate skeptic is easier to tune, and it needs sharp criteria of its own.
- Crews break on one shared task, on sequential work, on same-file edits and without a lead that validates results. Google's range runs from +80.8% to −70.0%.
- By vendor figures, crews cost several times what one agent does. Pay it when the job is worth more than the tokens and harder than one agent can reliably do, and give each role only the model it needs.